Resemble AI
Resemble AI generates synthetic voice, but its real strength now is verifying whether any voice, video, image, or text is authentic in the first place. Watermarking, deepfake detection, and identity tools built for organizations where trust isn't optional.
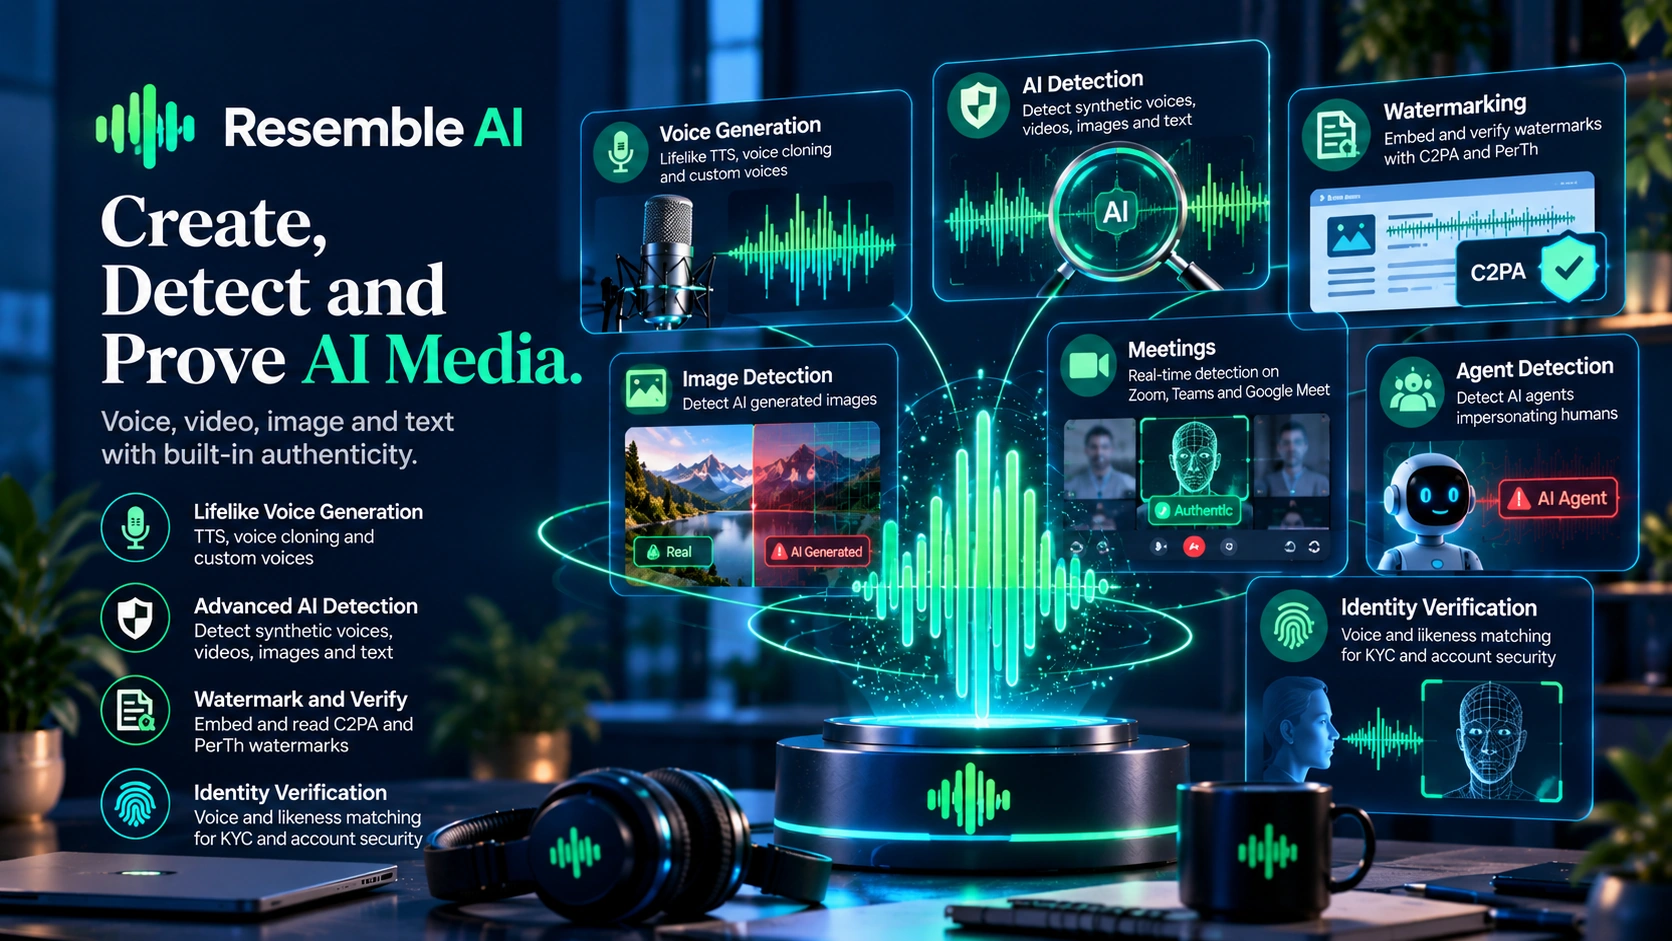
Resemble AI builds synthetic voice, and increasingly, it's just as focused on telling you whether any piece of audio, video, image, or text is synthetic in the first place. The company's center of gravity has shifted from pure voice generation toward verification at scale: deepfake detection across audio, video, and images through Resemble Detect, real-time detection of synthetic voices and faces on live video calls through Resemble Meetings, identity enrollment for KYC-style verification through Resemble Identity, and a watermarking system, PerTh Multimodal, that as of mid-2026 covers audio, video, image, and text, not just audio. Voice generation itself, including a newer model called Resemble Ultra, is still real, but it's now one input into this platform rather than the headline.
The Platform That Checks
Whether Voice Is Real.
Most tools in this category are built purely for creation. ElevenLabs optimizes for emotional realism and human-level performance. Murf AI focuses on structured production where timing and alignment matter more than expressiveness. Each is solving some version of the same question: how do you make AI voice sound better, faster, or more controllable.
Resemble AI still does voice generation, including a newer model called Resemble Ultra, built on xAI's model rather than its own. But the company's center of gravity has shifted toward a different question entirely: how do you verify, at scale, whether a piece of audio, video, image, or text is authentic, AI-generated, or tampered with.
That's a meaningfully bigger scope than "voice governance." The product line now includes deepfake detection across audio, video, and images; real-time detection of synthetic voices and faces on live video calls; identity enrollment for KYC-style verification; and a watermarking system that, as of mid-2026, covers audio, video, image, and text, not just audio.
This is where many Resemble AI reviews miss the bigger picture: they treat it as "ElevenLabs, but with extra security bolted on."
It's closer to the reverse. Voice generation is the part of the business that's easiest to describe. Detection, verification, and watermarking are where the company has actually been building, and for the specific question those tools answer, whether synthetic media can be identified and traced at scale, Resemble AI is one of the more complete platforms in the category.
Resemble AI isn't just asking "can we generate this voice." It's asking "can we tell when someone else did."
The First Session Looks
Like a Voice Tool.
Open Resemble AI for the first time and the surface feels familiar: a voice cloning interface, text-to-speech generation, playback controls, export options. You upload a sample, generate some audio, test the output. The voice quality is solid. The interface is clean. Nothing about this first layer feels different from any competent voice tool.
- Voice cloning from a sample, with reasonable fidelity
- Text-to-speech generation with emotional controls
- Speech-to-speech for real-time voice transformation
- Export options across common file formats
- Fast, reliable generation
Keep exploring and a second layer shows up that most voice tools don't have at all: verification workflows, watermarking controls, identity enrollment, deepfake detection, and a whole separate product, Resemble Meetings, for catching synthetic voices and faces on live video calls. None of this reveals itself in a casual first session, because it isn't built for a casual first session. It's built for teams that already know they need to verify what's real.
Unlike ElevenLabs, which tunes its interface around performance quality, or Murf, which tunes around production workflow, Resemble tunes around control and verifiability. The generation layer might sound competent but unremarkable on its own. The detection and watermarking layer is where the actual differentiation lives.
Resemble AI treats your voice, and increasingly any media you touch, as something that needs to be verifiable, not just something that needs to sound good.
Resemble AI in Action
Four official videos from Resemble AI's own YouTube channel, covering emotional voice building, IVR integration with Dialogflow, in-app voice cloning, and the deepfake detector.
Resemble AI's Real Product
Isn't Voice Generation. It's Verification.
Most reviews evaluate Resemble AI as a voice generation tool with some extra security features layered on top. That framing was already backwards when the product was mostly about watermarking one audio stream. It's more backwards now.
The core system runs on three stages: generate, verify, detect.
Create or clone voices, including through the newer Resemble Ultra model. Generation quality is solid but Resemble isn't trying to out-perform ElevenLabs on realism. It's competing on what happens after generation.
Embed ownership and identity into content through watermarking, now across audio, video, image, and text, using a system called PerTh Multimodal. These marks are imperceptible, survive format conversion and re-encoding, and read and write standards like C2PA and SynthID. This is not metadata tagging bolted on after the fact. It's a mark built into the content itself.
Identify synthetic media, not just synthetic voice, across audio, video, and images, using what Resemble calls a "DETECT-World" model. The same detection logic now runs in real time inside video calls through Resemble Meetings, and in a separate product aimed specifically at detecting AI agents impersonating humans in a session.
None of this is an add-on anymore. For Resemble AI, it's the product. Other tools in this category optimize for realism, expression, and ease of use. Resemble optimizes for trustworthiness, and it's unusual in this category because detection and verification are central to the product rather than secondary features.
Resemble AI is a tool where the security layer is part of the core product, not the footnote.
Six capabilities that define Resemble AI.
Generate, verify, and detect in one platform: generate voice with embedded identity, verify authenticity through multimodal watermarking, and catch unauthorized or synthetic content after the fact.
Not just audio: Resemble Detect analyzes audio, video, and images to flag content that's synthetic, altered, or inconsistent with what it claims to be.
Resemble Meetings catches synthetic voices and faces during live video calls on major platforms, aimed at the executive-impersonation and fraud scenarios that text-based detection can't catch.
PerTh Multimodal embeds imperceptible, tamper-resistant marks into audio, video, image, and text, and reads and writes standard provenance formats like C2PA and SynthID rather than inventing a closed system.
Cloning requires explicit consent workflows and usage tracking, and the newer Resemble Ultra model adds another generation option on top of Resemble's own.
Clean API access, on-premises and air-gapped deployment options, and role-based access controls, built for teams that can't just use a hosted SaaS tool.
G2 Community Reviews
From 20 verified users
At the time of this review, Resemble AI holds a 3.9/5 rating on G2 based on 20 verified user reviews. Here's what users consistently say, good and bad.
- User-friendly interface: easy to produce voiceovers without technical expertise. (11 mentions)
- Voice customization: human-like models with emotional depth and multilingual support. (11 mentions)
- Realistic, expressive voiceovers that hold up in marketing use. (10 mentions)
- Versatile, organic-sounding output across use cases. (9 mentions)
- Voice cloning that replicates a source voice effectively. (7 mentions)
- Pricing, especially for heavier usage. (7 mentions)
- Cost of premium features on top of the base plan. (6 mentions)
- Inconsistent output quality in some generations. (6 mentions)
- Sentence-length limits requiring longer text to be broken into segments. (4 mentions)
- Interface polish, with room to improve usability. (4 mentions)
This reflects 20 verified G2 reviews at the time of this writing. Visit G2 for the most current user feedback and individual review comments.
View all reviews on G2 →Resemble AI vs ElevenLabs
vs Murf AI
All three generate synthetic voice. What they optimize for, and increasingly, what else they build around that voice, is where they actually diverge.
| Capability | Resemble AI | ElevenLabs | Murf AI |
|---|---|---|---|
| Core optimization | Verification and authenticity, across voice, video, image, and text | Emotional realism, performance-grade delivery | Structured production and predictable voiceover workflows |
| Distinctive capability | Multimodal deepfake detection and watermarking built into the core platform | Strong emotional realism and expressive delivery | Built-in timeline editor and scene-based sync |
| Scope beyond voice | Detection and watermarking extend to video, image, and text content generally | Voice-focused | Voice-focused |
| Deployment options | Cloud, on-premises, and air-gapped, enterprise-focused | Cloud, API-first | Cloud, browser-first |
| Best for | Regulated industries, platforms needing to verify media at scale, fraud and impersonation risk | Audiobooks, narrative podcasts, performance content | Training, onboarding, corporate explainers, structured content |
Chatterbox: Resemble AI's
Open-Source Voice Models
Resemble AI splits its business in two. Everything covered so far, detection, watermarking, identity, Meetings, is the paid platform. Voice generation itself now mostly lives on the other side, under a free, open-source research arm called Voice AI Research. Chatterbox is the product of that arm.
Resemble states this split directly: Chatterbox and its other generative voice models are "open and free to build on under Voice AI Research, but are no longer offered as commercial paid products." In other words, the company gives away the voice generation, and sells the verification layer around it.
Chatterbox is a family of open-source voice models, released under the MIT license, so anyone can download it, self-host it, and use it commercially with no fee. The main variants include:
350 million parameters, English only, built for speed with sub-200ms latency. Supports paralinguistic tags like [cough], [laugh], and [chuckle] for more expressive delivery.
110 million parameters, English only, small enough to run about 3x faster than real time on an 8-core CPU, no GPU required.
500 million parameters, with 20+ languages in the core model and six dedicated language packs for priority languages and dialects.
The multilingual model still has uneven performance across languages, so Resemble recommends evaluating specific languages before production use.
One important detail is that every clip Chatterbox generates is watermarked by default, using the same PerTh watermarking technology behind Resemble's paid Watermarker product. The free, open model still carries the company's core idea into the open-source world. Even giving away voice generation for free, Resemble ships it pre-wired for verification.
Real-World Use Cases
for Resemble AI
Real-time voice transformation with identity tracking lets teams run conversational voice agents while keeping a verifiable record of what was generated and by whom.
Deepfake detection lets security teams check whether a clip claiming to be an executive or employee was actually generated by an authorized system.
Resemble Meetings runs detection in real time on Teams, Zoom, and Google Meet calls, aimed at catching a synthetic voice or face mid-call rather than after the fact.
Multimodal watermarking now covers video, image, and text as well as audio, giving brand and content teams a way to verify ownership and authenticity after publication across more than just voice.
Consent workflows built into cloning, plus the newer Identity product for enrollment and matching, give compliance teams an audit trail for whose voice or likeness was used, with what permission, and when.
A Few Things Worth
Knowing About Resemble AI
Synthetic media isn't just a creative capability. It opens up identity misuse, unauthorized cloning, reputational damage, and fraud. Resemble AI's current product line is largely built around managing that expanded risk.
For an individual creator, voice is content. For an organization, it's a brand asset, a legal exposure, and a compliance question. Without governance, scaling voice means scaling risk.
This isn't a tool for one-off content creation. Expect API usage, workflow integration, and real technical setup before it earns its place.
Resemble runs four tiers: Flex at $0/mo pay-as-you-go, Team at $350/mo ($280/mo billed annually), Business at $1,000/mo ($800/mo billed annually), and custom Enterprise pricing. On top of that, detection, watermarking, and identity features are metered separately (for example, audio detection runs $0.035/sec on Flex, dropping to $0.015/sec on Team and above). This pricing model is different from voice-generation tools that primarily meter characters or generated audio.
Resemble occupies a different position from ElevenLabs: its emphasis is verification and protection around synthetic media. Many organizations run both: a performance tool like ElevenLabs for the voice itself, Resemble for verification and protection around it.
Rolling out watermarking, detection, or identity verification touches approval processes and compliance documentation, not just an API call. It works best once an organization is actually ready to operationalize it.
Resemble AI under the hood, at a glance.
On-premises and air-gapped deployment options for organizations with strict data residency requirements.
Includes the newer Resemble Ultra model, built on xAI's model rather than Resemble's own.
Usage tracking and explicit approval workflows. First clone free, additional clones $2/mo each.
Covers audio, video, and images on a "DETECT-World" model architecture.
Live detection on Teams, Zoom, and Google Meet calls.
Covers audio, video, image, and text. Reads and writes C2PA and SynthID marks.
Voice and likeness enrollment and matching for KYC-style verification.
MIT licensed, free, run by Resemble's Voice AI Research arm. 26.7k GitHub stars at the time of this review.
Predictable behavior and security controls, built for secure deployment across applications.
Flex $0/mo pay-as-you-go, Team $350/mo ($280/mo annual), Business $1,000/mo ($800/mo annual), Enterprise custom, plus metered rates for detection, watermarking, and identity features.
What to Expect
Session by Session
Cloning, generation, and playback all work, output is competent, and the session usually ends with usable audio and the sense that the tool is functional but unremarkable.
Watermarking, consent workflows, detection tools. The product stops feeling like a voice generator and starts feeling like infrastructure. The value shifts from "this makes good voice" to "this lets us deploy voice, and other media, safely."
You start thinking about voice and media ownership, verification, and risk management. At this point Resemble has become the layer that makes synthetic media trustworthy, not just the layer that creates it.
Three Users
Resemble AI Was Built For
You need secure, compliant voice and media systems, and you treat voice and video as brand assets with legal implications. Watch out for operational complexity: adopting governance means workflow changes, not just a technical integration.
You're deploying synthetic voice or media inside a product where users generate and share content, and you need to verify authenticity and catch misuse. Watch out for integration effort: building governance into your product is more work than adding a generation API.
Finance, healthcare, government, media, anywhere unauthorized synthetic voice or video could cause real harm. Watch out for cost justification: the pricing reflects infrastructure, so make sure decision-makers understand they're buying verification, not just audio.
Who Should
Look Elsewhere
Resemble prioritizes verification over everything else. Here's when that trade-off works against you.
Resemble AI FAQ
The Resemble AI Verdict
Resemble AI made one deliberate choice: prioritize trust over generation.
That choice shows up everywhere in the product. Watermarking that now reaches audio, video, image, and text, not just voice. Detection that runs on recorded media and on live video calls alike. An identity layer that treats consent and verification as part of the workflow, not an afterthought. A generation layer, now including the newer Resemble Ultra model, that exists to produce voice, while the rest of the platform exists to make sure that voice, and increasingly any synthetic media, can be checked.
Its focus is different from ElevenLabs' emphasis on emotional realism, and from Murf's emphasis on production workflow integration. It's trying to answer a different question better than most other tools in the category attempt at all: how do you tell what's real, at scale, across voice, video, image, and text.
For organizations considering Resemble AI, the value is not simply generating synthetic media. It is being able to verify where specific content came from, how it was generated, and whether it can be trusted.
Use it when that proof is the point. Use a generation-first tool when it isn't.
Try Resemble AI for your enterprise
Enterprise solution for voice and media verification. Contact for a demo and current pricing.
 Contact Resemble AI →